example.com/path/to/article
000 points · username · 0 hours ago
example.com1160 points · 669 comments · 12 days ago · bratao
simonw
jampa
- Real world knowledge (when a thing opens and closes, the geographic region, historical facts). It's also the best at taking a cluster of places and working out a visiting order.
- Photo ranking (which photo should be the hero). Gemini can tell whether a photo is of the thing or of the view from it.
- Document parsing (extracting the relevant trip info from PDFs).
If you use LLMs for anything other than coding, I definitely recommend not discounting Gemini like I did just because other models are more popular.
mattlondon
https://artificialanalysis.ai/models/gemini-3-8-flash shows an intelligence score of 59, the same as Opus 5 medium!
Wow - for a flash model this seems to benchmark powerfully. Remains to be seen what it is like to use.
simonw
Here are the 3.7 pelicans for comparison: https://tools.simonwillison.net/markdown-svg-renderer.html?u... - high cost 8.4387 cents
(I think thinking level low is a regression on 3.8 compared to 3.7.)
simonw
Gemini Flash is also pretty cheap, so it's a great family for performing media analysis, like extracting structured data from images and video.
EFLKumo
brap
These sort of fast and cheap models are great for tasks that are verifiable and can be retried infinitely (like coding), you can basically get frontier results with a good harness (at a fraction of the time and money).
a11r
mattlondon
I eagerly wait more info but sounds like Deepmind without Demis calling the shots has been unleashed and are operating at full speed? Shocker!
At this point it is a meme of course, but where is 3.5 Pro :)
j-bu
Kind of wild that they haven't (successfully) pretrained a base model since Jan-25.
andai
kamranjon
I have been testing 3.7 flash against 3.5 flash and it seems to lose every time in overall latency. Every benchmark I've seen seems to suggest the opposite[1] - that 3.7 flash is significantly (at times 2x) faster than 3.5 flash - but I have never been able to prove this out in real world use cases.
Has anyone found their latency numbers to actually be accurate? Is this why they've toned it down in this release? For context, I'm testing larger generation payloads that take 8-10 seconds in 3.5 flash and 15-25 seconds in 3.7 flash. Lowest reasoning settings in both cases.
1: https://artificialanalysis.ai/?speed=intelligence-vs-speed&m...
abixb
One aspect of model releases that don't get discussed as much are the cache invalidation (changes in underlying architecture, weights, or tokenizers); I assess Google seems to be squeezing the maximum out of the last 'Pro' version they released with 3.1 back in February.
Small models cataching up with their bigger siblings are fantastic news.
xnx
raincole
Unless they have an even more powerful Gemini Pro in the oven...?
nxdmum
I always enjoy interacting with Gemini . When i ask it questions about designing a new model etc - it's always the most helpful and encouraging . I really want to thank the Google team for this and their happy positive models they generate.
I use gemini flash after a round of deliberation between Sol and Kimi these days on the main plan . Kimi 2.7 paired with Gemini 3.5/4.6/3.7 flash has been my implementer - Kimi k3 and Sol 5.6 have been my planners and code reviewers.
I would have ideally like Anthropic and was on their USD 200 plan - but after they didnt sign the letter for Open source models - i dropped my subscription . Wont make a difference to their lives.
But Sol is great . Combined with Kimi K3 for adversarial plan reviews - you get robust plans . And Sol as a reviewer for Gemini/kimi 2.7 - you get great edge case handling and robust code.
I also integrated muse 1.2 - on the contributor tier - and I Just saw facebook release 1.3 muse . this is great news. The training im permitting is my thanks to FB for releasing the open source models of the past ! Thank you !
lysecret
PaulStatezny
I've complained plenty on here about Claude verbosity and TED-talk phrasing, and it seems by contrast Gemini has already arrived at the dream end-state of Claude from a prose standpoint.
Sometimes I ask for feedback, and I get back a list of multiple-choice options as if it's already ready to go. If I indicate I'm thinking about doing something, sometimes it'll just...do it. (Not in an annoying way.)
It seems very geared toward action in a way that's completely refreshing coming from months steeped in Claude essays.
jerkstate
pampas
meh2frdf
throwa356262
"available to trusted defenders through our new Fairwind Program"
leopoldj
adbachman
Is this weakness in their training regimen the impact of operating under regulatory frameworks for too long?
npn
And even when searching for internet, it still cannot suggest a up-to-date approach to the problem.
For example I'm using crystal, it recently revamped the concurrency/parallel model. Even using web search, gemini still does not aware of the new feature and still give the outdated code.
I'm sure my crystal usage is not the unique case here.
atemerev
henry-xli
hmate9
AM1010101
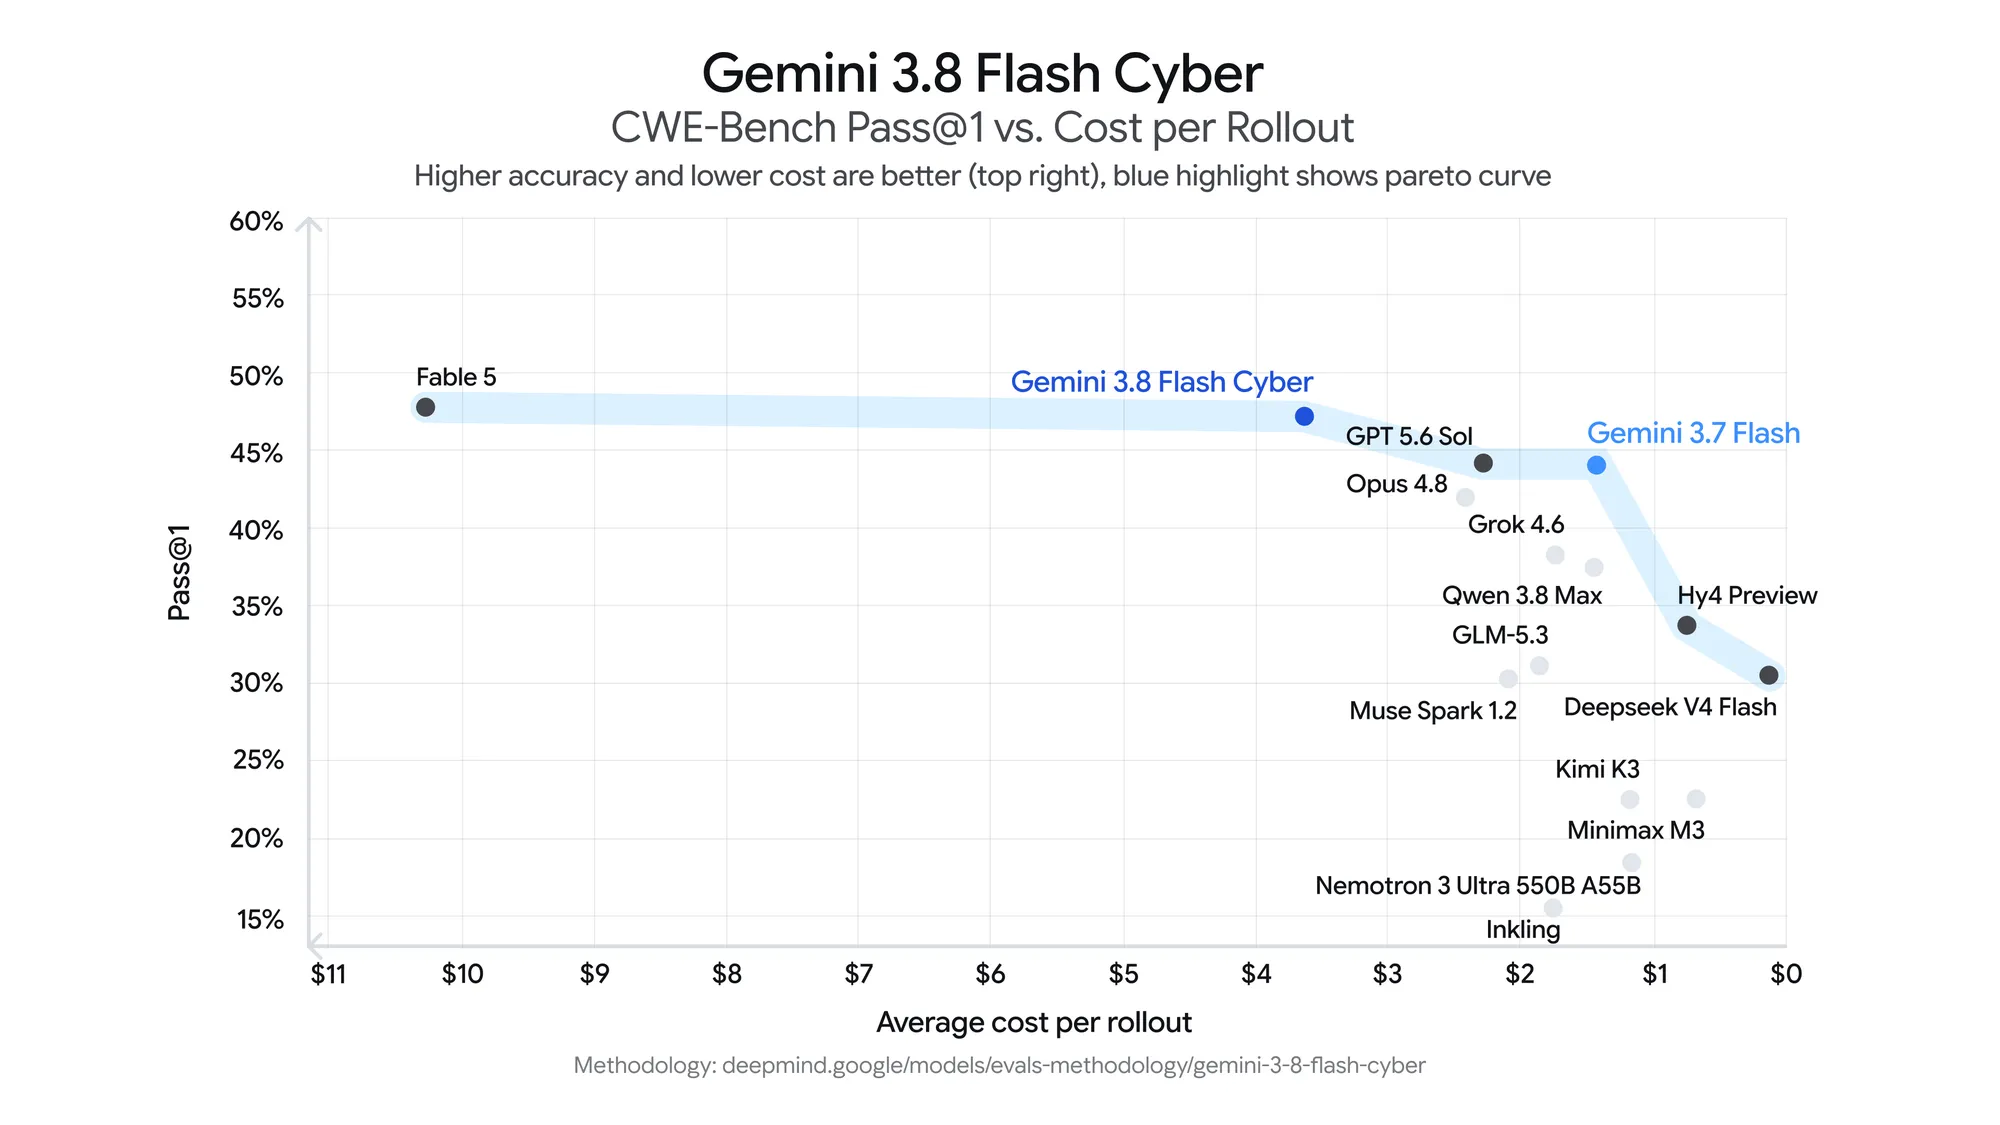
If I had to pay per token I would probably consider using this (they seem to be on the pareto of performance) but not being able to use opencode with a subscription is not really something I'm realistically going to do when claude and codex are around. Also never gotten along well with gemini-cli / antigravity-cli.
buntp
f311a
gere
I also used it for a an app for my Garmin watch, and it wasn't good. The code was compiling, but functionality was totally broken and even with a lot of steering it wasn't able to make it work. GLM 5.3-flash instead was up for it and the code wasn't bad at all. I am curious to see if 3.8 is an improvement in this use case.
wjellyz
andreygrehov
- Flash-Lite
- 3.6 Flash [new]
- 3.1 Pro
The above is why i don't use LLM products from Google. If the model is not available right this minute (heck, hours before the release!), then I'm not gonna bother getting back to it tomorrow, because tomorrow I'll be playing with the new model from OAI/Anthropic.
pimeys
sfink
(I guess the only relevance here is that if your problem matches a model's strengths, then you can do fine with a model that is several generations out of date.)
mowmiatlas
virajk_31
Do they make it intentionally to look previous model less superior than current models? or these are the real numbers when re-ran the benchmark..?
2001zhaozhao
(By high volume I mean things like "main app just updated with XYZ commits, please scan XYZ plugins and surface any compatibility issues")
eis
3.7 used 64M on high: https://artificialanalysis.ai/models/gemini-3-7-flash 3.8 used 120M on high: https://artificialanalysis.ai/models/gemini-3-8-flash
Even their own chart showed more than 2x higher cost compared to 3.7: https://storage.googleapis.com/gweb-uniblog-publish-prod/ima...
eis
3.7 used 64M on high: https://artificialanalysis.ai/models/gemini-3-7-flash 3.8 used 120M on high: https://artificialanalysis.ai/models/gemini-3-8-flash
Even their own chart showed more than 2x higher cost compared to 3.7: https://storage.googleapis.com/gweb-uniblog-publish-prod/ima...
yipinwong
Flash 3.8 seems like where I can specify Flash3.8 as the coding model as part of agent workflow.
The video recognition is especially impressive as they got all of Youtube to train from.
- Def people who has to queue video recognition jobs to use the model.
lpolovets
FpUser
"safety performance" - this starting to get long in the tooth. Gemini cut programming session 3 times for "safety reasons" yesterday for mentioning image generation (I need to generate bunch of those for infinite zoom virtual training app experience). After I got creative and managed to trick it to answer t was of course because "think of a children"
And in my other app I was debugging and using OpenAI to optimize some path it cut me off numerous times because it did not like JIT functionality (this is my commercial business rule evaluation engine that compiles rules to executable code inside the app to increase performance using asmjit library)
I am basically paying for them to waste my tokens and time on these 2 tasks
jetter
throw10920
dismalaf
leumon
speak_plainly
dyauspitr
Yesterday I asked for food stop on my road trip 45 minutes from the current time and it gave me some options, but then I changed my mind and specifically asked for Asian restaurants and it completely forgot about the 45 minutes and gave me the closest Asian restaurant to me.
kelvinjps10
pwython
XCSme
[0]: https://aibenchy.com/compare/google-gemini-3-6-flash-high/go...
tagalog
I have an eval harness that runs every Thursday to determine which models are the current best for a few different client workflows. And since May(?) flash has slowly been taking over more and more stuff to the point it is now 100% on 8 out of 11 document extraction flows with the other 3 being a Flash / Opus 4.8 mix for high value stuff where cost is less of a factor.
_aavaa_
or1gaminal
nharada
kelvinjps10
ddp26
What's the simplest explanation?
satvikpendem
aff-vasileva
asdaqopqkq
k9294
I just ran two light tasks on my codebase and got 100% of the weekly limits of a Pro plan blown away. Is Ultra plan any different? Because on Codex it wouldn't affect my Max plan at all, I think it would have been below 1% othese usage.
spwa4
Galorious
jpau
Similarly Qwen3.8-Max was updated in just 30 days (to the 0902 release) and Muse Spark in just 28 days (to the 1.3 release).
A year ago iterative releases were every 3-6 months. At what point will they reach nightly candidates?
alex1138
amazingamazing
therealmarv
But it's bad at code reviews (maybe it's the harness agy cli?). Could not get it to same quality level on reviews like Opus, GPT 5.6, Grok. Even tried special code review skills but no luck.
sreekanth850
hmokiguess
keytalker
I switched my subagent-swarm skill(https://github.com/bazelment/yoloswe/blob/main/.claude/skill...) to the 3.8 model and has been very happy so far. It has been driving the swarm to produce steady outcome, and more importantly, the exec communication is also crystal clear, instead of filling with jargons and long sentences.
akurilin
TechRemarker
drivebyhooting
As much as I like the speed and interactivity, I really don’t trust it
algoth1
ASinclair
mrbonner
robertwt7
sva_
koalaman
anilakar
[deleted]
dcchambers
ldm0
centaurz
tabs_or_spaces
I think the worst thing we can do is have loyalty towards models. I used to be loyal towards Claude, and my viewpoint changed dramatically when I used codex.
I highly recommend that if you are someone who only used one model so far, that you really give another model a shot and see how it goes. It's very eye opening and gives you a more holistic perspective.
Vendor locking is a big problem when it comes to models, and I hope the software world doesn't do this blindly.
sergiotapia
DonsDiscountGas
newppc
prometheus1992
maxnevermind
1 what is tesla cybercab plan to address legal implications of accident that will happen? who is going to be responsible for them when they happen? are they covered by tesla insurance or some other insurance? are there any official plan/statements around that?
2 what was the name of the experiment they started in san antonio tx when some cars didn't have a driver? what was the results of it? did they expand the operations? it was much smaller than waymo, is it growing? how it is related to robotaxi?
It is not able to connect the dots that I keep asking about Tesla in 2nd prompt and spit out some unrelated stuff. Really? How it can be that bad? Gemini 3.1 Pro model works fine in this case btw. I thought maybe it is about knowledge cut over date and it doesn't know about those events from 2025 but it seems it has the knowledge up to March 2025. Top 10 in Intelligence on artificialanalysis ladies and gentlemen.
Foobar8568
lgl
They're apparently evolving slower than most SOTA models but "slow and steady wins the race" is probably still a thing.
And since Google doesn't depend exclusively on AI models, they can probably afford to "wait and see" where all this craze is heading.
im_soul
dongking
thrdbndndn
It still uses 3.6 Flash for example.
Surac
1saadcodes
fitsumbelay
realist_not
mohamedkoubaa
_s_a_m_
HardCodedBias
The Google brand remains powerful on HN!
I’m shocked.
bbstats
theplumber
advenn
[deleted]
firemelt
levelZero
schmorptron
jdw64
OG_BME
johnnyApplePRNG
I am continually impressed with Gemini's chat responses, which encourages me to test their agentic capabilities and... no... no... and no... every single time.
It's terrifying watching it, really.
barapa
casey2
Razengan
zuzululu
so its fast sure and decent at non coding usage but for developers nothing can really top sol or fable.
even grok 4.6 is so so and i would not choose 3.8 flash over it.
yipinwong
Mashimo
deanc
mythz
So just another mid-tier flash model, nothing exciting, but Antigravity has very generous quotas so it's a good workhorse model when your Claude/OpenAI subs run out.
And whilst it's a fast model, having to baby sit through and approve prompts every few seconds ends up making it slower than the Auto approve modes of Claude/ChatGPT - they definitely need an auto approve mode.
[deleted]
tacomonstrous
[deleted]
shuvrojit
coffeecoders
A recent example - I searched for how to unsubscribe from Pearson emails. Google Search "AI Mode" confidently gave me a sequence of steps along the lines of Settings > Profile > Email preferences > Unsubscribe.
Of course, I looked for an unsubscribe link before asking Google. None of those options existed. The correct answer was there is no way to unsubscribe through the account, so I just blockthe emails instead.
I've run into this pattern quite a few times. AI Mode seems to make up things all the time.
greenowl
Are you people truly this excited about this crap? I mean I guess if you work for Google or Anthropic or whatever I could see it??? Otherwise, are these just bot comments?
Here's what I got for 1.8 cents and 13 seconds from the prompt "make me a cool thing in html":
https://gisthost.github.io/?6a77bc41a81718c6aaa10d4ab243c59f
Transcript here (it was part of a chat): https://gist.github.com/simonw/b6149a49d327164d67d62c3d12992...